Critical review showing why statistical models produce false positives and why deterministic provenance is superior. For the past several years, the prevailing strategy for combating synthetic media has been detection: build better classifiers, train on larger datasets, identify artifacts faster than generative models can eliminate them. The logic seemed sound. If AI can create deepfakes, AI can also detect them. Except it hasn't worked. The value of provenance ultimately depends on whether organizations can turn evidence into confident decisions. Synthetic Proof helps examine that broader trust picture across AI content and workflows. Detection-based approaches have reached an operational ceiling. They struggle against modern generative models, degrade rapidly as those models improve, and offer no mechanism to verify authenticity when detection fails. Organizations deploying deepfake detectors today are discovering what researchers have known quietly for s...
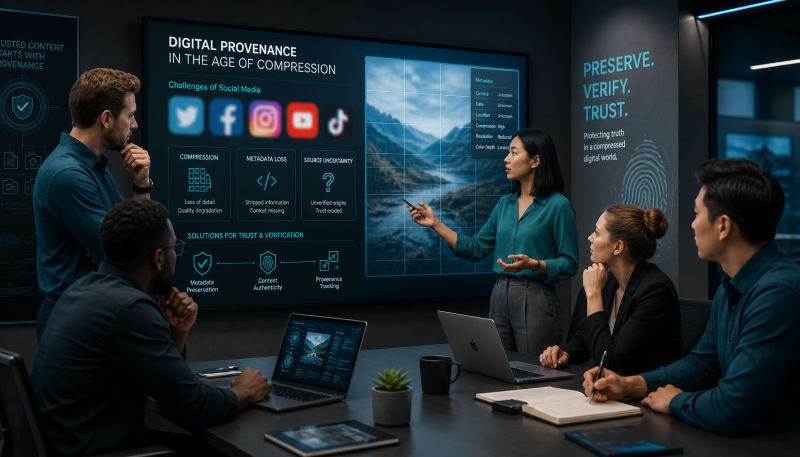
Practical troubleshooting guide for brand managers and creators sharing certified assets online.
A forensic photographer captures evidence at a crime scene, embedding GPS coordinates, timestamps, and chain-of-custody data into the image metadata. Within hours, a news outlet screenshots the image from a social media post and republishes it. The metadata is gone. The provenance is severed. What remains is pixels without proof.
This scenario plays out thousands of times daily across newsrooms, legal practices, insurance claims departments, and creative studios. The problem isn't malicious tampering—it's structural fragility. Digital assets are increasingly valued not just for what they depict, but for what they can prove about their origin, creation, and handling. Yet the systems we use to share them systematically strip away the very information that establishes their trustworthiness.
The value of provenance ultimately depends on whether organizations can turn evidence into confident decisions. Synthetic Proof helps examine that broader trust picture across AI content and workflows.
As organizations build workflows around AI-generated content, synthetic media detection, and digital provenance, they're discovering that metadata—the invisible foundation of digital authenticity—doesn't survive contact with the platforms where content actually circulates.
Why Social Platforms Strip Metadata By Design
Social media platforms compress, resize, and reprocess uploaded images for performance and consistency. This isn't an oversight. It's an architectural decision optimized for speed, bandwidth, and user experience at planetary scale.
When an image is uploaded to Twitter, Instagram, or LinkedIn, the platform typically:
- Strips EXIF and XMP metadata to reduce file size
- Removes embedded cryptographic signatures
- Recompresses the image using platform-specific encoding
- Eliminates color profiles and non-visual data layers
- Discards provenance chains embedded in the file structure
The result is a visually similar image with none of the verifiable history that might establish its authenticity, ownership, or compliance with editorial standards.
Screenshots introduce a second layer of destruction. When a user captures a screen image of content, they're creating an entirely new file—a visual rendering that preserves appearance but obliterates technical provenance. The screenshot looks identical to the original, but forensically, it's a completely different artifact.
For organizations building trust infrastructure around digital content, this creates a foundational problem: the moment an asset enters the primary distribution channels where audiences actually encounter it, its verifiable history disappears.
The Growing Cost of Metadata Fragility
The consequences aren't hypothetical. Legal teams increasingly struggle to authenticate digital evidence when metadata has been stripped through routine sharing. News organizations can't verify the provenance of user-submitted content that's been screenshotted multiple times. Insurance adjusters face fraudulent claims supported by images with no technical history.
In creative industries, the problem compounds. A photographer embeds copyright information and licensing terms in image metadata. A client downloads the image, shares it internally via Slack, and another team member screenshots it for a presentation. The licensing information is gone. Months later, the image appears in an unauthorized commercial context, and there's no technical trail connecting it to the original creator.
As AI-generated content proliferates, the stakes escalate. Organizations implementing policies around synthetic media disclosure rely on metadata to flag AI-generated images. But if that metadata doesn't survive the distribution process, the disclosure becomes functionally meaningless. A properly labeled AI-generated image becomes indistinguishable from an unlabeled one the moment it's shared through standard channels.
This isn't just a technical inconvenience. It's a structural barrier to accountability in digital content ecosystems.
Why Traditional Watermarking Doesn't Solve Provenance
The obvious response—visual watermarking—addresses ownership visibility but not verifiable provenance. A visible watermark can be cropped, obscured, or removed. An invisible watermark embedded in pixel patterns survives some transformations but degrades under compression, resizing, and format conversion.
More fundamentally, watermarks don't carry structured provenance data. They might indicate ownership, but they don't establish:
- When and how the asset was created
- What tools or models generated it
- Who modified it and when
- What approvals or compliance checks it passed
- Whether it's been altered since a specific point in time
A watermark says "this belongs to someone." Provenance metadata says "here's the verifiable history of how this came to exist."
The distinction matters in contexts where proof, not just attribution, is required. Courtrooms, regulatory audits, editorial standards enforcement, and compliance verification all require evidence chains that watermarks can't provide.
Provenance Must Move Beyond the File
If metadata can't survive inside the file as it moves through distribution systems, provenance must be established outside the file.
This requires a conceptual shift. Instead of treating the digital asset itself as the container for its history, organizations are beginning to treat provenance as a parallel record—maintained separately but cryptographically linked to the asset regardless of how it's transformed.
The technical approach typically involves:
Cryptographic fingerprinting: Generating a unique hash of the original asset that remains constant even if metadata is stripped. This fingerprint can be registered in an external system before distribution.
Persistent identifiers: Assigning a globally unique identifier to the asset that connects it to an external provenance record, rather than embedding that record in the file itself.
Verification endpoints: Providing a lookup mechanism where anyone encountering the asset can verify its history, even if they only have a degraded screenshot or compressed version.
This model separates appearance from provenance. The image can be compressed, screenshotted, and shared freely. The provenance record remains intact and queryable through independent verification.
It's the difference between carrying your medical records in your pocket versus having them accessible through a verified system using your patient ID. The ID might be all you carry, but the full record is available when needed.
What External Provenance Actually Protects
Moving provenance outside the file creates resilience against the most common forms of unintentional data loss. A news organization registers an original photo's hash before publication. Days later, the image appears on social media, stripped of metadata and screenshot multiple times. The newsroom can still verify the image matches their original by checking the hash against their provenance record.
For AI-generated content, this approach enables persistent disclosure. An image generated by a synthetic media system is hashed and registered with a label indicating AI creation. Even after the image is compressed and shared, anyone can verify its synthetic origin by checking the hash—assuming they have access to the verification system.
In regulated industries, external provenance enables compliance verification without relying on fragile metadata. A financial services firm using AI to generate marketing imagery can prove to auditors that specific assets passed required approval workflows, even if the final distributed versions contain no embedded compliance data.
The limitation is discoverability. Embedded metadata travels with the file automatically. External provenance requires an intentional verification step. Someone must know to check, and they must have access to the verification system.
The Verification Gap Nobody's Solving
External provenance systems solve durability but create a new problem: who actually verifies?
Most people encountering a digital image online have no technical means to check its provenance, even if a robust external record exists. They see pixels. They don't see—and typically don't think to check—the cryptographic history.
This creates an asymmetry. Organizations producing content can maintain rigorous provenance practices. But if the audiences consuming that content never verify it, the provenance becomes functionally invisible.
Some emerging approaches attempt to bridge this gap:
Platform-level verification integrations: Social platforms could theoretically display provenance indicators for registered assets, pulling data from external verification systems. This remains largely aspirational, with limited adoption.
Browser extensions: Tools that automatically check encountered images against provenance registries, flagging AI-generated content or verifying authenticity. Adoption depends on users installing and trusting the extension.
QR codes or visible verification prompts: Adding a scannable element that directs viewers to external provenance records. This reintroduces visual modification, which many use cases want to avoid.
Each approach trades off between verification accessibility and content integrity. Making provenance easily checkable often requires altering the asset itself, which reintroduces the fragility problem from a different angle.
TrustOps Is Where Provenance Becomes Operational
For organizations moving beyond theoretical provenance into operational implementation, the challenge shifts from technology to practice. This is where TrustOps—the emerging discipline of operationalizing trust and verification across AI and digital content workflows—becomes relevant.
TrustOps treats provenance as infrastructure rather than a feature. It asks: what processes ensure digital assets are registered, tracked, and verifiable throughout their lifecycle, regardless of how they're shared or transformed?
This typically involves:
- Registration workflows that capture provenance data at creation
- Automated hashing and external storage of cryptographic fingerprints
- Integration points with content management and distribution systems
- Verification mechanisms accessible to both internal teams and external stakeholders
- Audit trails that connect published assets back to approval and compliance records
The goal isn't perfect security—it's creating enough friction and verifiability that provenance becomes a practical tool rather than an aspirational ideal.
Organizations implementing TrustOps practices around content provenance are typically motivated by compliance requirements, legal risk mitigation, or editorial standards enforcement. They're not trying to prevent all possible manipulation. They're trying to establish a verifiable record that survives the messy reality of digital distribution.
Final Thoughts
Metadata fragility isn't a bug—it's a consequence of how digital distribution systems are built. Platforms optimize for scale and performance. Users share content through whatever tools are convenient. Screenshots and compression happen by default, not by exception.
For organizations that need to preserve provenance through this gauntlet, the solution isn't more durable embedding—it's architectural separation. Provenance becomes infrastructure: maintained externally, cryptographically linked, and queryable regardless of what happens to the file itself.
This creates new capabilities but also new requirements. External provenance systems must be trusted, accessible, and integrated into workflows where verification actually matters. Without adoption at the point of consumption, even perfect technical provenance remains invisible to the people who might need it most.
The shift happening now is from treating provenance as metadata—fragile, embedded, easily lost—to treating it as a parallel record that exists independently of the asset. That's not just a technical evolution. It's the foundation of how trust infrastructure is beginning to work in environments where files themselves can't be trusted to carry their own history.
The Practical Position
The prevailing architecture of digital distribution was built for reach, not for proof. As organizations attempt to layer trust infrastructure onto platforms designed to strip it away, they're discovering that provenance isn't a feature you add to content—it's a property that must be preserved through the entire lifecycle, or rebuilt outside the channels where authenticity matters most.
— Kevin Marsh, Editor-in-Chief
SYNTHETIC PROOF
FROM PROVENANCE TO OPERATIONAL TRUST
Understand Your AI Trust Gap
Synthetic Proof helps teams evaluate verification, provenance, prompt risk, and digital media trust through independent audits and structured findings.
Explore Synthetic ProofSynthetic Proof
Verified — Editorial Layer
This content has passed editorial verification for clarity, accuracy, and trust alignment.
Editor-in-Chief: Kevin Marsh
Verification Status: PASSED
Verification Status: PASSED
Comments
Post a Comment