Critical review showing why statistical models produce false positives and why deterministic provenance is superior. For the past several years, the prevailing strategy for combating synthetic media has been detection: build better classifiers, train on larger datasets, identify artifacts faster than generative models can eliminate them. The logic seemed sound. If AI can create deepfakes, AI can also detect them. Except it hasn't worked. The value of provenance ultimately depends on whether organizations can turn evidence into confident decisions. Synthetic Proof helps examine that broader trust picture across AI content and workflows. Detection-based approaches have reached an operational ceiling. They struggle against modern generative models, degrade rapidly as those models improve, and offer no mechanism to verify authenticity when detection fails. Organizations deploying deepfake detectors today are discovering what researchers have known quietly for s...
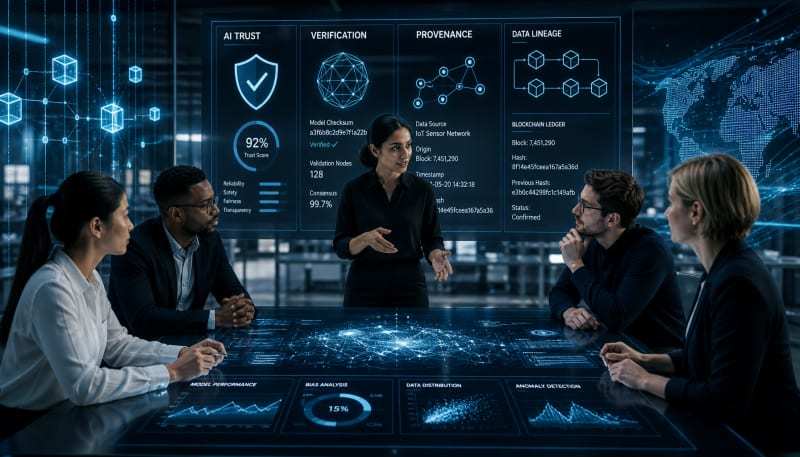
A tactical evaluation guide comparing different open standards and proprietary trust frameworks to help leaders choose the right stack.
Enterprise media organizations are discovering that AI-generated content creates a paradox: the same technology that accelerates production also erodes the authenticity signals audiences have relied on for decades. A news outlet can publish a thousand articles faster than ever, but without provable origin and transparent modification history, each piece carries less inherent credibility than traditional content. The question is no longer whether to use AI in media workflows—it's how to maintain trust while doing so.
This tension is driving something more significant than policy updates or editorial guidelines. Organizations are building trust architectures—integrated technical systems that verify, track, and prove the authenticity of both synthetic and human-created content throughout its lifecycle. These aren't theoretical frameworks. They're operational infrastructure being deployed today by media companies, enterprises, and platforms that recognize verification can't be an afterthought.
As content history becomes a governance concern, organizations need more than another metadata field. Synthetic Proof provides an independent way to assess provenance, verification, and wider AI trust risk.
Why Media Provenance Became an Infrastructure Problem
Five years ago, provenance was primarily a metadata problem. Attach some tags, maybe sign a hash, call it authenticated. The assumption was that content moved through relatively linear workflows with clear handoffs and limited modification.
AI-assisted production destroyed that model.
A single article might begin with AI research summarization, move through human editing, incorporate AI-generated visuals, undergo automated fact-checking, receive additional human review, and get republished across multiple platforms—each step potentially altering, enhancing, or transforming the original. Without structured provenance capture at each transition, reconstructing what happened becomes archeology rather than auditing.
The problem compounds when you consider scale. A media organization might produce hundreds of pieces daily, each following unique workflows involving different AI models, human contributors, and approval chains. Manual documentation fails immediately. Spreadsheets become obsolete before they're shared. What's needed isn't better record-keeping—it's infrastructure that captures provenance as a native byproduct of production itself.
This is where trust architectures emerge. They're not documentation systems. They're technical frameworks that make verification, attribution, and modification tracking automatic, cryptographically verifiable, and operationally embedded.
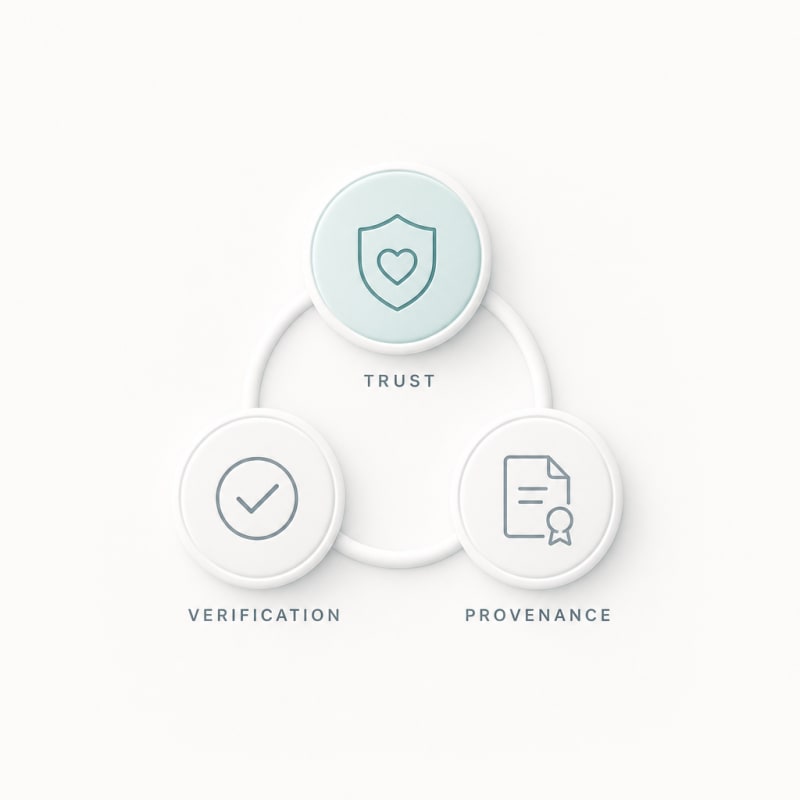
The Three Layers Every Trust Architecture Requires
Building effective trust infrastructure for hybrid human-AI media workflows requires addressing three distinct but interconnected challenges: verification, provenance, and presentation.
Verification: Proving What Actually Happened
Verification answers a deceptively simple question: how do you prove this content is what you claim it is?
For human-created content, verification traditionally relied on institutional authority and editorial processes. For AI-generated content, those signals don't exist. A piece of synthetic media has no inherent authorship, no creative intent, and no accountability unless explicitly architected into the system.
Modern verification frameworks capture technical proof at the moment of creation—model identifiers, generation parameters, timestamps, and cryptographic signatures that establish an immutable record. When a media organization uses AI to generate an image, the verification layer doesn't just save the image. It records which model created it, what prompt was used, what safety filters were applied, and who authorized the generation.
This isn't metadata that can be stripped away or altered. It's cryptographically bound evidence that moves with the content and can be independently validated without trusting the publisher's word alone.
Provenance: Tracking Transformation Through Workflows
Verification tells you where content came from. Provenance tells you what happened afterward.
Most enterprise media doesn't stay in its original form. Articles get updated. Images get cropped. Videos get shortened for social distribution. AI might enhance an image, a human might revise a headline, automated systems might translate content into multiple languages. Each transformation is legitimate—but each also changes what the content is.
Provenance architectures create an immutable chain documenting every modification. Not just "this was edited," but specifically: what changed, who or what changed it, when, and under what authority. When an AI model upscales an image, the provenance layer captures the original resolution, the model used, and the parameters applied. When a human editor revises AI-generated text, the system records what was synthetic, what became human-authored, and where the boundary exists.
This continuous tracking creates something increasingly valuable: a complete, auditable history that proves content integrity without requiring anyone to simply trust the publisher.
Presentation: Making Trust Visible and Verifiable
The most sophisticated verification and provenance infrastructure fails if audiences can't access or understand it. Presentation layers translate cryptographic proof into human-comprehensible transparency.
This might mean visible indicators showing which parts of an article were AI-generated versus human-written. It could involve embedded verification that lets readers independently confirm an image's origin and modification history. It increasingly means providing machine-readable attestation that platforms, regulators, and automated systems can validate without human interpretation.
The challenge is balancing transparency with usability. Show too little and trust remains opaque. Show too much and you overwhelm readers with technical detail they can't interpret. Effective presentation layers provide graduated disclosure—simple trust indicators for general audiences, detailed technical proof for those who want to verify independently.
Why Synthetic and Authentic Content Require Unified Infrastructure
One of the most important architectural insights emerging from early trust implementations: you cannot build separate systems for synthetic versus authentic content.
The distinction sounds logical initially. AI-generated content needs verification that human journalism doesn't require. But modern media workflows don't respect clean boundaries. An article might be researched by AI, written by humans, illustrated with AI-generated images that a human designer modified, and fact-checked through a combination of automated and manual review.
Which parts need provenance tracking? All of them.
Creating separate systems for synthetic and authentic content introduces several problems. First, it requires editors to correctly classify content at every step—a surprisingly difficult task when AI and human contributions are deeply integrated. Second, it creates gaps at the boundaries where content transitions between systems. Third, it suggests that authentic content doesn't require the same verification rigor as synthetic content, which undermines the entire trust proposition.
Unified trust architectures treat all content as requiring provenance, regardless of origin. The infrastructure captures creation context, tracks modifications, and maintains chains of custody whether the content came from a generative model, a photojournalist's camera, or collaborative human-AI workflows. This approach doesn't just simplify implementation—it creates consistent trust signals that audiences can understand and rely on.
Where Standards Meet Reality
The Coalition for Content Provenance and Authenticity (C2PA) has provided important technical specifications for embedding provenance in media files. But specifications aren't architectures. They're building materials.
Organizations implementing trust infrastructure quickly discover that C2PA compliance solves part of the problem—specifically, how to cryptographically sign and verify media assets. What it doesn't solve is how to integrate verification across content management systems, publishing workflows, AI model deployments, editorial tools, and distribution platforms. It doesn't address how to capture provenance from internal AI systems that weren't designed with verification in mind. It doesn't handle the operational question of who signs what, when, and with what authority.
This gap between standards and operational reality is where trust architecture actually gets built. It requires integrating cryptographic signing into content creation tools, building provenance capture into AI inference pipelines, creating governance workflows that determine what attestations mean, and developing presentation layers that make verification accessible.
The organizations succeeding here aren't just implementing C2PA. They're building comprehensive trust infrastructure that uses C2PA as one component within a larger operational framework.
The Operational Questions Architecture Must Answer
Technical specifications provide capabilities. Trust architectures must answer operational questions that determine how those capabilities get used.
Who has signing authority? When a generative AI system creates content, which cryptographic keys sign the provenance data? What happens when that content gets edited—does the original signature remain valid, or does a new attestation replace it? If multiple parties contribute to content creation, whose attestation takes precedence?
What gets tracked? Comprehensive provenance could theoretically document every pixel change and word revision. But that creates storage burdens, performance impacts, and privacy concerns. Effective architectures define what level of granularity actually serves verification needs without creating operational overhead that makes the system unsustainable.
How does trust degrade gracefully? Not all content will flow through perfect verification workflows. Legacy content exists without provenance. External content arrives without attestation. Human error and technical failures will occur. Trust architectures need defined behavior for these cases—how to handle unverified content, how to present partial provenance, how to communicate uncertainty without destroying credibility.
These aren't technical questions. They're governance decisions that technical architecture must support. The organizations building sustainable trust infrastructure recognize this and design systems that make good governance technically enforceable rather than purely procedural.
Infrastructure That Scales With Automation
Manual verification worked when content production was measured in dozens of pieces per day. As AI accelerates production to hundreds or thousands, trust infrastructure must scale automatically or it simply won't happen.
This requirement is driving trust architecture toward what some organizations are calling TrustOps—applying the same automation, instrumentation, and continuous operation principles from DevOps to content verification and provenance.
Instead of editors manually documenting AI usage, the inference pipeline itself captures generation parameters and creates signed attestations. Instead of tracking modifications through email and shared documents, the content management system automatically records provenance as a byproduct of normal editing workflows. Instead of periodic audits to verify compliance, continuous monitoring provides real-time visibility into what content has verification coverage and what doesn't.
This operational approach transforms trust from a quality-assurance checkpoint into foundational infrastructure. Verification isn't something that happens to content before publication—it's something that happens continuously as content is created, modified, and distributed.
Final Thoughts
Trust architectures represent a fundamental shift in how media organizations think about authenticity. The question is no longer simply whether content is real or synthetic—it's whether you can prove what it is, where it came from, and what happened to it.
The organizations building this infrastructure today aren't waiting for universal standards or regulatory mandates. They're responding to immediate business needs: maintaining audience trust while scaling AI-assisted production, meeting emerging platform requirements for content verification, and preparing for regulatory environments where provenance will likely become mandatory rather than optional.
The trust layer is being built. The question is whether it gets built thoughtfully, with proper architecture and governance, or whether it gets assembled reactively under regulatory pressure. The former creates sustainable competitive advantage. The latter creates compliance overhead. That difference in approach will define which organizations successfully navigate the hybrid human-AI media landscape ahead.
SYNTHETIC PROOF
FROM PROVENANCE TO OPERATIONAL TRUST
Understand Your AI Trust Gap
Synthetic Proof helps teams evaluate verification, provenance, prompt risk, and digital media trust through independent audits and structured findings.
Explore Synthetic ProofSynthetic Proof
Verified — Editorial Layer
This content has passed editorial verification for clarity, accuracy, and trust alignment.
Editor-in-Chief: Kevin Marsh
Verification Status: PASSED
Verification Status: PASSED
Comments
Post a Comment