Critical review showing why statistical models produce false positives and why deterministic provenance is superior. For the past several years, the prevailing strategy for combating synthetic media has been detection: build better classifiers, train on larger datasets, identify artifacts faster than generative models can eliminate them. The logic seemed sound. If AI can create deepfakes, AI can also detect them. Except it hasn't worked. The value of provenance ultimately depends on whether organizations can turn evidence into confident decisions. Synthetic Proof helps examine that broader trust picture across AI content and workflows. Detection-based approaches have reached an operational ceiling. They struggle against modern generative models, degrade rapidly as those models improve, and offer no mechanism to verify authenticity when detection fails. Organizations deploying deepfake detectors today are discovering what researchers have known quietly for s...
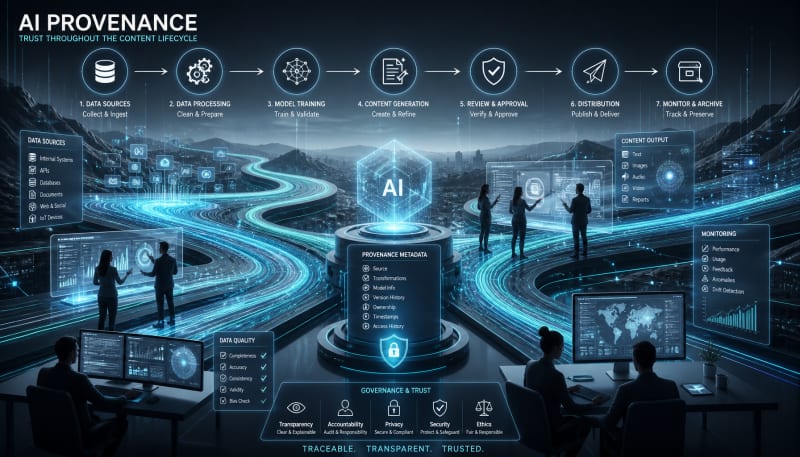
Learn how provenance evolves from creation through publication.
Most organizations approach AI provenance as a point-in-time problem. They track the origin of a dataset, verify a model before deployment, or authenticate a piece of content at publication. But content doesn't exist at a single moment—it evolves through creation, transformation, distribution, and reuse. Each stage introduces new actors, new modifications, and new trust questions. The real challenge isn't capturing provenance once. It's maintaining it across an entire lifecycle.
As AI-generated and AI-modified content becomes infrastructure rather than novelty, the lifecycle perspective matters more than the snapshot. A press photo gets cropped and color-corrected. A training dataset gets filtered and augmented. A contract template gets customized across departments. Without continuous provenance, trust erodes at each handoff—and by the time content reaches its final use, no one can confidently answer what happened along the way.
As content history becomes a governance concern, organizations need more than another metadata field. Synthetic Proof provides an independent way to assess provenance, verification, and wider AI trust risk.
Provenance Breaks at the Handoff Points
The weakest moments in content integrity occur during transitions. When a generative model produces an image, initial provenance data might exist—metadata about the model, timestamp, prompt hash. But when that image enters an editorial workflow, gets imported into a design tool, undergoes color correction, and finally gets published to a content management system, most provenance signals vanish.
Each tool in the chain operates independently. The design application doesn't inherit metadata from the generation platform. The CMS doesn't preserve transformation history from the design tool. The distribution network doesn't carry forward attribution details from the CMS. By the time the content appears in front of an end user, the provenance trail resembles archaeology rather than documentation.
This isn't a theoretical gap. Newsrooms struggle to maintain attribution when images pass through multiple editors. Legal teams can't reconstruct how a contract clause was generated when it's been modified across versions. Compliance officers face audits without reliable records of which model produced which recommendation. The problem isn't that provenance doesn't exist—it's that it doesn't travel.
What Lifecycle Provenance Actually Captures
Lifecycle provenance isn't simply longer metadata. It's a structural shift from recording attributes to recording transformations. Instead of asking "where did this come from," it asks "what happened to this, and who was responsible at each stage?"
At creation, provenance captures generative context: the model, the input parameters, the timestamp, the operator. At transformation, it records what changed: cropping, filtering, re-rendering, augmentation. At distribution, it logs where content traveled and under what permissions. At reuse, it maintains the chain when content becomes input to another process.
This creates accountability across handoffs. If an AI model generates a legal summary, and a paralegal edits it, and an attorney approves it, and the summary gets cited in a filing, the provenance record should reflect all four stages. Not just the origin. Not just the final state. The path between them.
Technically, this requires persistent identifiers that survive format changes, cryptographic mechanisms that prevent retroactive editing, and standardized schemas that different systems can interpret. More importantly, it requires infrastructure designed around continuity rather than capture.
Why Point-in-Time Verification Isn't Enough
Organizations often treat verification as a checkpoint. Verify the model output before it enters the workflow. Verify the final content before publication. But content changes between checkpoints, and those changes carry risk.
A verified image might be authentic at generation but altered in post-production. A verified dataset might be clean at ingestion but contaminated during preprocessing. A verified model output might be accurate initially but modified by downstream automation. Point-in-time verification creates a false sense of security because it doesn't account for what happens in between.
Lifecycle provenance makes intermediate states visible. If content is verified at creation and again at publication, but provenance shows undocumented transformations in between, that gap becomes a signal. It doesn't automatically mean something went wrong—but it means someone should look. The absence of continuity becomes meaningful.
This matters particularly in regulated industries. Financial services firms must demonstrate that AI-generated risk assessments haven't been manipulated between model output and executive review. Healthcare organizations must show that diagnostic support content wasn't altered between generation and clinical use. Media companies must prove that attributed quotes weren't modified between transcription and publication. None of these assurances work without lifecycle visibility.
Where the Current Infrastructure Fails
Most content systems weren't designed for provenance continuity. They track versions, store metadata, and log access—but they don't preserve transformation history across system boundaries.
The problem is architectural. Content management systems operate in silos. Design tools export files without embedded history. APIs strip metadata during transfer. Cloud storage flattens provenance into file properties that don't migrate. Even when individual tools capture rich provenance data, that data rarely survives the next platform.
Some organizations attempt to solve this with external logging—tracking content movement through separate audit systems. But external logs don't travel with content. When an asset leaves the controlled environment, the log stays behind. The content itself becomes untethered from its history.
Emerging standards like C2PA attempt to address this by embedding provenance directly into content files using cryptographic manifests that persist across transformations. This is infrastructure-level thinking: provenance becomes part of the content itself rather than a parallel record. But adoption remains inconsistent, and many critical platforms don't yet support manifest preservation during processing.
Provenance as Operational Practice, Not Just Technology
Technology enables lifecycle provenance, but operational discipline sustains it. Organizations need policies that treat provenance continuity as a requirement, not a feature.
This means procurement standards that prioritize provenance-preserving tools. It means workflow designs that include provenance handoff protocols at each transition point. It means training teams to understand that modifying content without updating provenance records creates compliance exposure. It means treating provenance breaks the same way security teams treat access control failures—as incidents requiring investigation.
The discipline also requires deciding what level of granularity matters. Not every pixel adjustment needs cryptographic attestation. But significant transformations—content that changes meaning, scope, or context—should update the provenance record. Organizations must define their own materiality thresholds based on risk tolerance and regulatory requirements.
This operational thinking aligns with the emerging TrustOps discipline, where trust capabilities become integrated into content workflows rather than bolted on at endpoints. The goal isn't perfect auditability of every change. It's sufficient visibility to answer trust questions when they arise: Was this modified? By whom? Under what authority? With what tools?
The Reuse Problem
Content doesn't die at publication. It gets repurposed, excerpted, remixed, and fed back into new processes. Lifecycle provenance must account for reuse—both authorized and unauthorized.
When AI-generated content becomes training data for another model, the new model inherits provenance obligations from the source material. When a research report gets summarized and the summary gets quoted, the quote should maintain a connection to the original generation context. When marketing content gets translated and localized, each variant should preserve attribution to the source.
This creates complex provenance graphs rather than linear chains. A single asset might have multiple derivative versions, each with its own transformation history. A dataset might draw from hundreds of sources, each with distinct provenance requirements. Managing this without centralized infrastructure becomes impractical at scale.
The reuse challenge also raises jurisdictional questions. If content was generated under one regulatory framework and reused under another, which provenance requirements apply? If a European publisher uses AI-generated content from a U.S. provider, whose compliance standards govern the provenance record? These aren't just technical questions—they're legal and operational ones that organizations are only beginning to address.
Provenance Is Moving From Documentation to Infrastructure
Early provenance efforts focused on documentation—creating comprehensive records of content origins and transformations. The next generation focuses on infrastructure—building systems where provenance continuity is automatic rather than manual.
This shift mirrors earlier infrastructure evolutions. Version control moved from documentation practice to embedded tooling. Access management moved from policy manuals to identity infrastructure. Provenance is following the same path, moving from optional metadata to foundational capability.
Platform providers are beginning to recognize this. Cloud storage services are adding native provenance tracking. Content management systems are integrating cryptographic attestation. AI platforms are embedding generation metadata that downstream tools can consume and extend. The technology is becoming infrastructure rather than feature.
But infrastructure only works when it's interoperable. Provenance records need standardized schemas so different tools can read and update them. Cryptographic methods need consistent implementation so verification works across platforms. Policy frameworks need common vocabulary so organizations can communicate requirements to vendors.
Industry coalitions are forming around these standards, but adoption remains uneven. Organizations serious about lifecycle provenance increasingly find themselves specifying it in vendor contracts, requiring API support for provenance preservation, and building integration layers when tools don't natively support continuity.
Final Thoughts
The shift from point-in-time provenance to lifecycle provenance reflects a deeper maturity in how organizations think about AI-generated content. Early concerns focused on detecting fakes and attributing sources. Those concerns remain valid, but they're insufficient for content that lives, changes, and gets reused across complex workflows.
Lifecycle provenance requires infrastructure that doesn't exist universally yet. It requires operational practices many organizations haven't formalized. It requires cross-platform standards that are still emerging. But the direction is clear: as AI becomes a routine part of content creation and transformation, provenance must become routine infrastructure rather than exceptional documentation.
Organizations building content operations today should assume that lifecycle provenance will eventually be required—by regulators, by customers, by partners, or by their own risk management needs. The question isn't whether to build provenance continuity into workflows. It's whether to build it proactively or scramble to retrofit it later when the gaps become liabilities. The content lifecycle is already here. The provenance infrastructure is catching up.
The Practical Position
Provenance that disappears at the first handoff isn't provenance—it's decorative metadata. Organizations that treat verification as a moment rather than a thread will struggle to answer the only question that matters during an incident: what actually happened between creation and consequence. Trust isn't inherited from origins; it's maintained through transitions.
— Kevin Marsh, Editor-in-Chief
SYNTHETIC PROOF
FROM PROVENANCE TO OPERATIONAL TRUST
Understand Your AI Trust Gap
Synthetic Proof helps teams evaluate verification, provenance, prompt risk, and digital media trust through independent audits and structured findings.
Explore Synthetic ProofSynthetic Proof
Verified — Editorial Layer
This content has passed editorial verification for clarity, accuracy, and trust alignment.
Editor-in-Chief: Kevin Marsh
Verification Status: PASSED
Verification Status: PASSED
Comments
Post a Comment