Learn why organizations are investing in verification instead of detection alone. For years, the fight against synthetic media manipulation followed a familiar pattern: researchers identified deepfake artifacts, built detection models around those signatures, and deployed them across platforms. Detection accuracy improved. Conferences celebrated breakthroughs. The industry felt like it was winning. Then generative AI became exponentially better at eliminating the very artifacts those systems were trained to find. As synthetic media improves, confidence increasingly comes from layered evidence rather than a binary label. Synthetic Proof helps organizations evaluate that evidence in context. What's emerging isn't simply a technical gap that better detection can close. It's a fundamental shift in how organizations must approach digital trust. The old model—detect manipulated content after it's created—assumes defenders can keep pace with attackers....
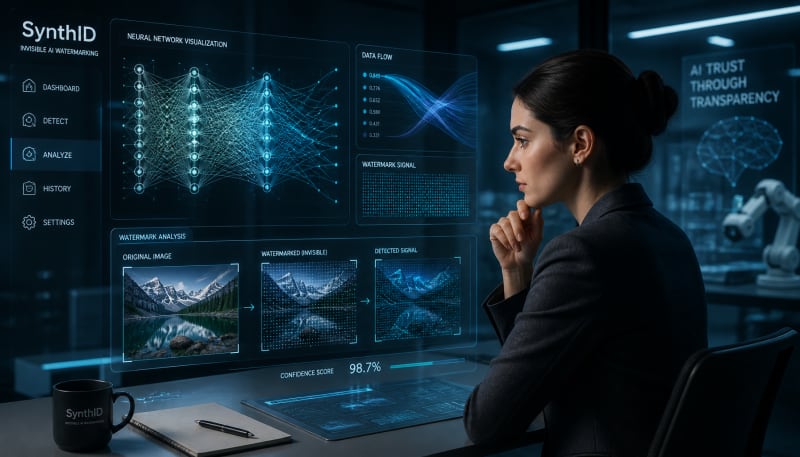
How DeepMind embeds imperceptible, edit-resistant signals into AI text, audio, image, and video.
When Google DeepMind released SynthID to the public a few years ago, the announcement represented something more significant than another research project becoming available. It marked the moment when one of the world's leading AI labs acknowledged that provenance—the ability to verify the origin and authenticity of digital content—had become an operational necessity rather than an academic curiosity.
SynthID is Google DeepMind's invisible watermarking system for AI-generated content. Unlike metadata tags or visible markers that can be stripped away, SynthID embeds imperceptible patterns directly into images, audio, video, and text during the generation process itself. The watermark survives cropping, compression, filters, and other common modifications that typically destroy traditional marking systems.
Content Credentials and attestation can strengthen transparency, but they represent only part of the trust landscape. Synthetic Proof helps organizations evaluate how these signals interact with verification, prompts, and governance.
What makes SynthID noteworthy isn't just the technology. It's what the technology represents: a fundamental acknowledgment that AI systems now require built-in provenance capabilities, not as an afterthought but as core infrastructure.
The Watermark That Survives Transformation
Traditional digital watermarks face a straightforward problem: they break easily. Crop an image, compress a video, or convert audio formats, and the watermark often disappears. This fragility makes them impractical for real-world content workflows where files routinely undergo transformation.
SynthID takes a different approach. Rather than adding information on top of existing content, it modifies the generation process itself to embed imperceptible patterns that become intrinsic to the content's structure.
For images, SynthID alters pixel values in ways that remain statistically detectable even after modification. For audio, it introduces subtle changes to the waveform that persist through compression and conversion. For text—which presents the hardest technical challenge—it influences the probability distribution of token selection during generation, creating patterns that remain detectable even when text is paraphrased or edited.
The technical achievement here is significant. The watermark needs to be robust enough to survive real-world modification while remaining imperceptible enough that it doesn't degrade quality. It must be detectable by verification systems but resistant to removal by adversarial actors who know it exists.
Why Google Built This Now
Google didn't build SynthID to solve a theoretical problem. The company built it because the absence of reliable content provenance had become a liability across multiple dimensions.
First, there's regulatory pressure. Governments worldwide are moving toward mandatory disclosure requirements for AI-generated content. The EU AI Act includes provisions for transparency in synthetic media. California passed legislation requiring disclosure of AI-generated political content. China requires watermarking of AI-generated material. These aren't proposed frameworks—they're implemented policy.
Second, there's platform liability. When social networks, news organizations, and content platforms cannot distinguish between human-created and AI-generated material, they face increased risk of manipulation, misinformation campaigns, and regulatory penalties. SynthID provides a mechanism for attribution that scales with the volume of content these platforms process.
Third, there's market differentiation. As generative AI becomes commoditized, the ability to verify content origin becomes a competitive advantage. Organizations adopting AI tools increasingly ask not just "can this generate good content?" but "can we prove where this content came from?"
Google open-sourced parts of SynthID and integrated it into Google Cloud's AI services, making it available beyond Google's own products. This move signals something important: the company recognizes that provenance infrastructure only works at scale when it becomes an industry standard rather than a proprietary advantage.
What SynthID Reveals About Watermarking's Limits
SynthID represents the current state of the art in content watermarking, but understanding its capabilities requires understanding its constraints.
The system works best when content is generated using tools that have SynthID built in. It cannot retroactively watermark existing content, and it cannot mark content created by models that don't incorporate the watermarking process. This creates a fundamental challenge: SynthID can verify content from participating systems, but it cannot prove the absence of AI generation for unmarked content.
For text specifically, the watermarking becomes less reliable when content undergoes significant editing or paraphrasing. While the system can detect patterns in machine-generated text, heavy human revision can degrade the signal. This isn't a flaw—it's an inherent tradeoff. A watermark robust enough to survive extensive human editing would need to be intrusive enough to potentially affect text quality or creative freedom.
More fundamentally, watermarking addresses only one dimension of the provenance challenge. It can identify content generated by a specific system, but it doesn't capture the full context: what prompt was used, what training data influenced the output, what modifications occurred after generation, or what human oversight was applied.
Watermarks answer the question "was this created by an AI system?" They don't answer "should I trust this content?" or "was this created responsibly?"
Where Watermarking Fits in the Trust Infrastructure
SynthID is best understood not as a complete solution but as one layer in an emerging trust infrastructure for AI-generated content.
Watermarking provides detection. It creates a technical mechanism for identifying content origin at scale. This matters enormously for platforms processing millions of files daily, where manual review is impossible and metadata-based systems are too fragile.
But detection alone doesn't create trust. Knowing that an image was AI-generated doesn't tell you whether it's being used appropriately, whether it misrepresents something factual, or whether it complies with relevant policies and regulations.
This is where provenance systems extend beyond watermarking into broader verification infrastructure. Organizations increasingly need not just to detect AI content but to maintain continuous records of how that content was created, what inputs influenced it, how it was modified, and what review processes it underwent.
The emerging architecture looks less like a single watermark and more like layered verification: watermarking for detection, cryptographic signing for authenticity, structured metadata for context, and audit systems for compliance. Each layer addresses different questions that organizations need answered as they operationalize AI at scale.
The Standardization Question Nobody Has Solved
One of the most significant unresolved challenges in AI watermarking isn't technical—it's organizational.
For watermarking to work as trust infrastructure, it requires coordination across competing platforms, research labs, and commercial vendors. Every major AI provider would need to implement compatible systems. Verification tools would need to recognize watermarks from multiple sources. Standards bodies would need to define interoperable specifications.
This hasn't happened yet. Adobe has Content Credentials. Microsoft has its own provenance initiatives. OpenAI has experimented with various detection approaches. Google has SynthID. These efforts often operate independently, creating fragmented ecosystems where verification works within specific platforms but not across them.
The C2PA (Coalition for Content Provenance and Authenticity) represents the most significant cross-industry standardization effort, bringing together technology companies, news organizations, and camera manufacturers around shared specifications. SynthID can work alongside C2PA standards, embedding watermarks while also supporting cryptographic signing and metadata standards.
But adoption remains uneven. Until watermarking becomes as standardized as file formats or network protocols, its effectiveness as universal trust infrastructure remains limited.
What Organizations Should Actually Do With This
For organizations deploying generative AI, SynthID and similar watermarking systems present both an opportunity and a strategic question.
The opportunity is straightforward: tools that automatically watermark generated content reduce the operational burden of disclosure and attribution. They provide a technical foundation for policy compliance, particularly as regulatory requirements expand.
The strategic question is harder: what role should watermarking play in your broader trust architecture?
Organizations with high-stakes AI deployments—in regulated industries, public-facing content, or sensitive applications—are discovering that watermarking alone doesn't satisfy their governance requirements. They need to demonstrate not just that content was AI-generated, but that it was generated responsibly, reviewed appropriately, and deployed in compliance with relevant policies.
This shifts the conversation from "should we watermark?" to "how does watermarking integrate with our verification, audit, and compliance systems?" The answer increasingly involves treating provenance as infrastructure rather than feature—building or adopting systems that maintain continuous chains of custody from generation through deployment.
Final Thoughts
SynthID represents a meaningful technical achievement in making AI-generated content identifiable at scale. Its robustness, imperceptibility, and integration into production systems make it one of the most practical watermarking approaches currently available.
But the more important story isn't the watermark itself—it's what the existence of SynthID signals about where AI infrastructure is heading. When one of the world's leading AI research organizations invests significantly in provenance technology and open-sources it for industry adoption, that's an acknowledgment that trust capabilities have become foundational rather than optional.
The challenge now isn't whether organizations need provenance infrastructure. It's whether they'll build it intentionally as part of their AI operations, or retrofit it reactively as regulatory and market pressures intensify. Watermarking provides one essential layer of that infrastructure, but the complete architecture requires something more comprehensive: systems that maintain verifiable records of AI content throughout its lifecycle, from generation through modification to deployment.
Organizations that recognize this early—that treat provenance as infrastructure rather than afterthought—are positioning themselves for a market increasingly defined by questions of trust, verification, and accountability. Those that don't will find themselves scrambling to retrofit governance capabilities into AI systems that were never designed with verification in mind.
That's the real lesson of SynthID. Not that watermarking has been solved, but that the industry has collectively recognized that solving it matters.
SYNTHETIC PROOF
BEYOND A SINGLE TRUST SIGNAL
See the Wider Trust Picture
Synthetic Proof helps organizations assess trust signals across AI content, prompts, media, and operational workflows.
View Trust and Audit OptionsSynthetic Proof
Verified — Editorial Layer
This content has passed editorial verification for clarity, accuracy, and trust alignment.
Editor-in-Chief: Kevin Marsh
Verification Status: PASSED
Verification Status: PASSED
Comments
Post a Comment