Learn why organizations are investing in verification instead of detection alone. For years, the fight against synthetic media manipulation followed a familiar pattern: researchers identified deepfake artifacts, built detection models around those signatures, and deployed them across platforms. Detection accuracy improved. Conferences celebrated breakthroughs. The industry felt like it was winning. Then generative AI became exponentially better at eliminating the very artifacts those systems were trained to find. As synthetic media improves, confidence increasingly comes from layered evidence rather than a binary label. Synthetic Proof helps organizations evaluate that evidence in context. What's emerging isn't simply a technical gap that better detection can close. It's a fundamental shift in how organizations must approach digital trust. The old model—detect manipulated content after it's created—assumes defenders can keep pace with attackers....
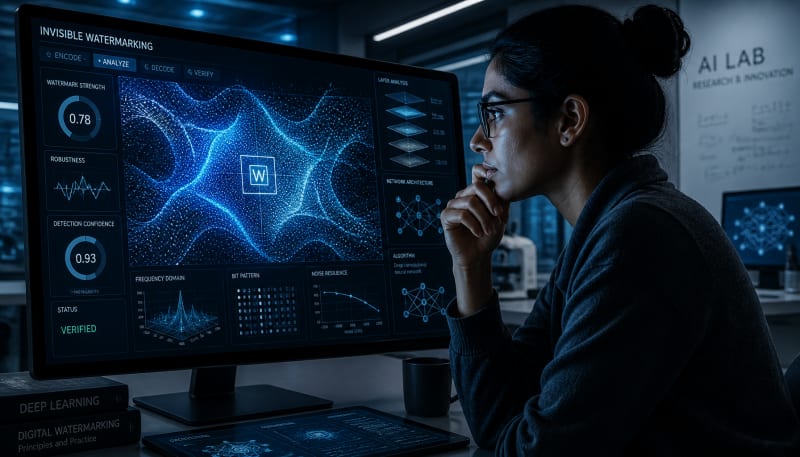
A Deep-tech exploration of latent-space modification and perceptual robustness against intentional manipulation.
Generative AI has fundamentally changed how content is created, but it has also introduced a problem that traditional security measures weren't designed to solve: how do you prove what's real when synthetic content is indistinguishable from authentic media? The answer emerging across major AI labs, technology platforms, and enterprises isn't metadata or visible stamps—it's invisible watermarking powered by deep learning.
Unlike traditional watermarks that can be cropped, compressed, or stripped away, deep learning-based invisible watermarks are embedded directly into the structure of generated content. They survive transformations that would destroy conventional markers. They operate at a level of sophistication that older techniques simply cannot match.
Content Credentials and attestation can strengthen transparency, but they represent only part of the trust landscape. Synthetic Proof helps organizations evaluate how these signals interact with verification, prompts, and governance.
This shift represents more than incremental progress. It marks the beginning of a technical foundation capable of scaling with AI-generated content itself—a foundation that may soon become essential infrastructure for anyone distributing, regulating, or verifying digital media.
Why Traditional Watermarking Fails Against Modern Manipulation
Traditional watermarking methods—whether visible overlays or frequency-domain techniques like LSB (Least Significant Bit) embedding—were designed for a different era. They assumed adversaries with limited computational resources and relatively simple attack vectors.
That assumption no longer holds.
Modern image manipulation tools, many themselves powered by AI, can easily detect and remove traditional watermarks. Compression algorithms destroy fragile embedded signals. Simple cropping or rotation can eliminate spatial markers. Even more sophisticated frequency-domain watermarks struggle against adversarial attacks specifically trained to isolate and neutralize them.
The problem intensifies when you consider the distribution environment. Content doesn't stay pristine. It gets screenshotted, re-encoded, compressed for mobile delivery, converted between formats, and shared across platforms with varying technical specifications. A watermark that can't survive this ecosystem is a watermark that can't be trusted.
Deep learning-based approaches solve this by learning robustness rather than engineering it.
How Neural Networks Learn to Hide Information in Plain Sight
Deep learning-based watermarking works fundamentally differently than rule-based embedding. Instead of manually specifying where and how to hide information, neural networks learn optimal embedding strategies through training.
The typical architecture involves an encoder network that embeds a watermark into content and a decoder network that extracts it. During training, these networks are exposed to various distortions—compression artifacts, noise, geometric transformations, even adversarial perturbations. The system learns to embed information in ways that survive these attacks while remaining imperceptible to human observers.
This approach produces watermarks that are simultaneously invisible and robust. The embedding process doesn't rely on predetermined frequencies or spatial locations. Instead, the network discovers representations that are intrinsically tied to the content's structure—representations that are difficult to remove without visibly degrading the content itself.
Some implementations go further, using adversarial training where one network attempts to remove the watermark while another learns to make it increasingly difficult to eliminate. This creates an arms race within the training process itself, producing watermarks hardened against sophisticated attacks before deployment.
Imperceptibility Through Learned Perceptual Optimization
One of the critical advances enabling invisible watermarking is perceptual loss functions. Rather than minimizing raw pixel differences, these loss functions optimize for perceptual similarity—how humans actually perceive images.
This allows watermarking systems to embed significantly more information without visible artifacts. The network learns which modifications are perceptually insignificant, concentrating changes in areas where human vision is less sensitive while avoiding modifications that would create noticeable distortions.
The result is content that appears identical to unwatermarked versions under normal viewing conditions, even when carrying robust identification signals.
Capacity, Robustness, and the Engineering Tradeoff
Deep learning-based watermarking doesn't eliminate fundamental tradeoffs—it manages them more intelligently.
Capacity refers to how much information can be embedded. Robustness measures how well that information survives manipulation. Imperceptibility ensures the watermark doesn't degrade content quality. Traditional techniques required manual balancing of these competing demands, often sacrificing one dimension to preserve others.
Neural approaches learn these tradeoffs dynamically. They can adapt embedding strength based on content characteristics—embedding more aggressively in textured regions where modifications are less visible, and more conservatively in uniform areas where changes would stand out. This content-aware adaptation allows higher overall capacity without sacrificing imperceptibility or robustness.
Recent implementations report capacity in the range of dozens to hundreds of bits while maintaining robustness against JPEG compression down to quality levels of 50 or lower, resolution changes, additive noise, and even partial geometric transformations. Some systems demonstrate resilience against print-and-scan attacks, where content is physically printed and then recaptured—a hostile environment that destroys most digital watermarks.
From Research Labs to Production Deployment
The transition from academic research to production systems has accelerated remarkably in the past two years. What was primarily a research curiosity in 2020 is now being deployed by major AI developers and content platforms.
Google's SynthID, developed by DeepMind, watermarks AI-generated images from Imagen and video from Veo. Meta has implemented invisible watermarking for Llama-generated content. OpenAI has explored watermarking for DALL-E outputs. These aren't pilot programs—they represent strategic investments in provenance infrastructure.
The deployment context matters. These systems aren't being built to catch individual bad actors. They're being built to create scalable verification infrastructure capable of handling billions of pieces of content. They're designed for environments where content will be manipulated, recompressed, and transformed in ways the original creators never anticipated.
This represents a significant shift in how the industry thinks about synthetic content. Watermarking is moving from optional feature to expected capability—part of responsible AI deployment rather than an afterthought.
The Adversarial Challenge That Won't Disappear
No watermarking system is unbreakable, and deep learning-based approaches are no exception.
Adversarial attacks specifically designed to remove learned watermarks are an active area of research. Some approaches train removal networks that learn to predict and eliminate watermark signals. Others use adversarial perturbations to corrupt the extraction process without significantly degrading content quality. Still others exploit the fact that watermarking systems must remain imperceptible, creating attack vectors specifically designed to stay within perceptual thresholds while disrupting embedded information.
The arms race is real. As watermarking techniques improve, so do removal techniques. This creates an ongoing cycle of attack and defense that shows no signs of resolving into a permanent solution.
But this doesn't mean invisible watermarking is futile. The goal isn't making removal impossible—it's making removal expensive, detectable, or quality-degrading. A watermark that requires significant computational resources to remove, or that cannot be removed without visible artifacts, still provides meaningful protection for many use cases.
The practical question isn't whether determined adversaries can defeat watermarks. It's whether watermarking raises the cost of deception sufficiently to matter at scale.
Watermarking as One Layer in a Larger Trust Architecture
Invisible watermarking is increasingly important, but it's not a complete solution to content authenticity.
Watermarks can verify that content came from a specific source or was generated by a particular model. They cannot verify that content hasn't been manipulated after generation. They don't establish context, intent, or chain of custody. They don't address content that was never watermarked in the first place.
This is why organizations building serious trust infrastructure treat watermarking as one component within broader provenance systems. Watermarks work alongside cryptographic signatures, metadata standards like C2PA, behavioral analysis, and verification workflows that combine multiple signals.
The value of invisible watermarking increases dramatically when integrated with complementary verification mechanisms. A watermark might trigger deeper inspection. Cryptographic signatures might validate the watermark itself. Provenance records might provide context that makes watermark detection more reliable.
This layered approach reflects a maturing understanding of digital trust. No single technique solves every problem. Effective verification requires multiple independent signals, each contributing to an overall confidence assessment.
The Regulatory Tailwind Accelerating Adoption
Technical capability alone doesn't drive adoption—incentives do. And regulatory pressure is creating powerful incentives for watermarking deployment.
The EU AI Act includes provisions requiring AI-generated content to be identifiable. California's AB 2655 mandates labeling of synthetic media. China's Generative AI regulations require watermarking and traceability. These aren't recommendations—they're compliance requirements with real enforcement mechanisms.
This regulatory environment is accelerating the shift from optional watermarking to expected infrastructure. Organizations that might have treated watermarking as a future consideration are now evaluating deployment timelines measured in quarters, not years.
The challenge is that regulation is moving faster than standardization. Different jurisdictions have different requirements. Different platforms have different technical implementations. This creates fragmentation that complicates cross-platform verification and international content distribution.
The industry needs interoperability frameworks that allow different watermarking systems to coexist and be verified across platforms. Without this, watermarking risks becoming a compliance checkbox rather than functional infrastructure.
Final Thoughts
Deep learning-based invisible watermarking represents a significant evolution in how digital provenance can be established. It solves real technical problems that traditional approaches couldn't address. It's being deployed at scale by major AI developers. And it's increasingly expected by regulators and platforms alike.
But watermarking alone won't solve the authenticity crisis created by generative AI. It's one capability within a broader trust architecture that requires cryptographic verification, provenance tracking, and operational discipline.
The organizations getting this right aren't just implementing watermarking—they're building comprehensive verification infrastructure that treats provenance as a strategic capability rather than a technical feature. They're thinking about how watermarks integrate with signing mechanisms, how extraction workflows scale across millions of verification requests, and how trust signals combine to create actionable confidence scores.
Invisible watermarking is becoming essential infrastructure. The question isn't whether to implement it—it's how to implement it as part of a trust architecture capable of scaling with AI itself.
SYNTHETIC PROOF
BEYOND A SINGLE TRUST SIGNAL
See the Wider Trust Picture
Synthetic Proof helps organizations assess trust signals across AI content, prompts, media, and operational workflows.
View Trust and Audit OptionsSynthetic Proof
Verified — Editorial Layer
This content has passed editorial verification for clarity, accuracy, and trust alignment.
Editor-in-Chief: Kevin Marsh
Verification Status: PASSED
Verification Status: PASSED
Comments
Post a Comment