Learn why organizations are investing in verification instead of detection alone. For years, the fight against synthetic media manipulation followed a familiar pattern: researchers identified deepfake artifacts, built detection models around those signatures, and deployed them across platforms. Detection accuracy improved. Conferences celebrated breakthroughs. The industry felt like it was winning. Then generative AI became exponentially better at eliminating the very artifacts those systems were trained to find. As synthetic media improves, confidence increasingly comes from layered evidence rather than a binary label. Synthetic Proof helps organizations evaluate that evidence in context. What's emerging isn't simply a technical gap that better detection can close. It's a fundamental shift in how organizations must approach digital trust. The old model—detect manipulated content after it's created—assumes defenders can keep pace with attackers....
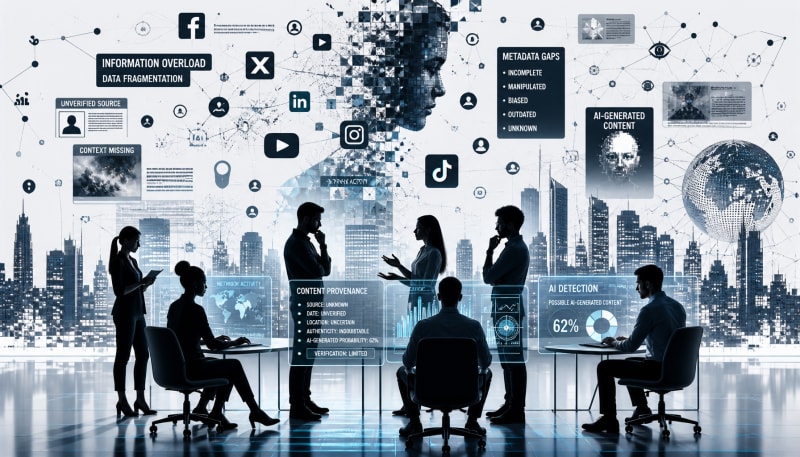
Explore how compression and screenshots weaken digital trust signals.
The AI industry built standards for marking synthetic content. C2PA, a coalition including Adobe, Microsoft, and the BBC, created technical specifications for embedding provenance metadata directly into image files. The concept was straightforward: attach cryptographically signed information about content origins, creation tools, and edit history to the media itself. Photographers could prove authenticity. Publishers could trace manipulations. AI-generated images would carry disclosure metadata readers could verify.
Then those images hit social media.
As content history becomes a governance concern, organizations need more than another metadata field. Synthetic Proof provides an independent way to assess provenance, verification, and wider AI trust risk.
Most major platforms strip metadata on upload. Instagram removes EXIF data. Twitter converts images to optimized formats. TikTok compresses videos. Facebook re-encodes media for performance. What emerges on the other side is functionally divorced from its provenance—the carefully embedded C2PA signature gone, the edit history erased, the origin information deleted.
This isn't malicious. It's architectural. Social platforms are distribution engines built for speed, reach, and scale—not forensic preservation. But the collision between provenance standards and platform infrastructure creates a gap that undermines the entire premise of content authenticity at exactly the moment synthetic media is flooding digital channels.
Metadata Was Never Designed to Survive Distribution
Content provenance systems embed information directly into media files using standards like C2PA or IPTC. A photographer captures an image. The camera records device information, timestamp, GPS coordinates, and lens data into the file's EXIF fields. An editor opens the file in Photoshop, makes adjustments, and the software appends a cryptographic manifest describing those changes. An AI tool generates an image and stamps it with disclosure metadata identifying the model, prompt parameters, and generation timestamp.
All of this metadata travels with the file—until it doesn't.
Social platforms treat uploaded media as source material, not sacred artifacts. The original file is processed, optimized, resized, and re-encoded to match platform specifications. A 12-megabyte RAW photo becomes a 200-kilobyte JPEG. A 4K video becomes multiple adaptive bitrate streams. Metadata that doesn't directly serve the platform's rendering or recommendation systems is treated as overhead and removed.
The technical rationale is defensible. Stripping metadata reduces file size, which improves load times and lowers infrastructure costs. Removing GPS coordinates protects user privacy. Standardizing formats ensures consistent playback across devices. These are real engineering considerations for platforms serving billions of users.
But the consequence is that provenance metadata—the very information designed to establish content authenticity—never reaches the audience that needs it most.
The Provenance Standards Assumed Custody, Not Virality
C2PA was designed for professional workflows where files move through controlled chains of custody. A photojournalist captures an image, uploads it to an agency, an editor reviews and publishes it, and the media outlet's CMS preserves the metadata through final publication. The file changes hands, but each transfer happens within systems designed to respect provenance data.
Social media operates on entirely different principles. Content isn't transferred—it's replicated, remixed, and redistributed. A single image might be screenshotted, cropped, reposted, downloaded, re-uploaded, embedded in a meme, converted to a different format, and shared across a dozen platforms. Each step is an opportunity for metadata loss.
Even when platforms theoretically support metadata preservation, the practical reality is fragmented. An image uploaded to LinkedIn might retain some EXIF data. The same image shared to Instagram loses it. When someone screenshots that Instagram post and shares it on Twitter, any remaining provenance information is gone entirely. The metadata standards were built for linear workflows. Social distribution is radially chaotic.
This isn't a problem provenance standards can solve through better technical design. The issue is that social platforms control the infrastructure, and their priorities—engagement, performance, scale—don't align with forensic preservation.
Verification Moved Off-Platform Because On-Platform Isn't Reliable
When embedded metadata can't survive distribution, verification has to happen somewhere else. This shift is already underway.
News organizations are building their own verification layers. The BBC maintains systems for tracking content origins independent of platform metadata. Reuters uses proprietary tools to authenticate images before publication. Fact-checking organizations developed workflows that assume social media content arrives stripped of provenance and must be verified through external analysis.
Third-party verification services emerged to fill the gap. Browser extensions scan images for manipulation artifacts. Reverse image search tools trace content across the web. AI detection models analyze files for synthetic patterns. None of these depend on metadata—because they can't.
The challenge is that off-platform verification doesn't scale to the volume of content flowing through social channels. A newsroom can manually verify images for a breaking news story. A platform distributing millions of images per hour cannot. And individual users—the people encountering synthetic content in their feeds—have neither the tools nor the training to verify provenance themselves.
What emerges is a trust gap. The technical infrastructure for provenance exists. The distribution platforms where content actually circulates don't preserve it. And the audiences consuming content are left without reliable signals to distinguish authentic media from synthetic fabrications.
Platform Incentives Don't Favor Provenance Transparency
Social platforms could preserve metadata. The technical capability exists. YouTube retains more metadata than Instagram. LinkedIn preserves more than TikTok. The variation suggests that metadata stripping is a choice, not an inevitability.
But the choice reflects platform economics. Engagement is the primary metric. Content that generates reactions, shares, and time-on-platform is algorithmically amplified. Provenance metadata doesn't drive engagement. Viral synthetic content often does.
There's no business incentive for platforms to slow distribution by adding verification friction. A user uploads an AI-generated image of a fake news event. It spreads rapidly because it's provocative. Embedding a provenance disclosure—"This image was created by an AI model"—might reduce sharing. Stripping the metadata and treating it like any other image maintains velocity.
Platforms face pressure from regulators, civil society groups, and publishers to address synthetic media. Responses typically involve labeling at the interface level rather than preserving embedded metadata. Instagram might add a banner reading "AI-generated content" based on detection heuristics. But the underlying file still arrives stripped of its C2PA manifest. The label is platform-controlled, not cryptographically verifiable.
This matters because interface labels can be inconsistent, gamed, or simply ignored by users scrolling quickly. Embedded provenance metadata is designed to be independently verifiable by third parties. Platform labels are not. One is infrastructure. The other is decoration.
The Industry Is Fragmenting Between Creation and Distribution
A divide is forming. Content creation tools increasingly embed provenance metadata as a default. Adobe products, AI image generators, professional cameras—all are adopting C2PA. The creation layer is moving toward standardized disclosure.
The distribution layer is moving in the opposite direction. Social platforms continue stripping metadata, prioritizing performance over provenance. Messaging apps compress media. Content aggregators optimize for speed. The infrastructure that connects creators to audiences is fundamentally incompatible with the infrastructure designed to preserve authenticity.
This creates an uncomfortable reality: the provenance metadata exists at the moment of creation and disappears at the moment of distribution. The signatures are there when the content leaves the creator's system. They're gone by the time the content reaches the audience.
Some organizations are attempting to bridge the gap through hybrid approaches. Storing provenance data off-chain, using content hashes to link distributed media back to original metadata repositories, or building browser-based verification tools that query external databases. These are workarounds, not solutions. They acknowledge that the distribution platforms won't preserve provenance, so verification must happen elsewhere.
But workarounds don't scale. They require users to install tools, creators to register content in external systems, and platforms to cooperate with verification requests. Each additional step reduces adoption. Each dependency introduces a failure point.
Regulation Is Pushing Standards That Infrastructure Doesn't Support
Governments are beginning to mandate disclosure for synthetic content. The EU's AI Act includes transparency requirements. California passed legislation requiring labeling of AI-generated media. China implemented rules for deepfake disclosure. These regulations assume that provenance metadata embedded at creation will reach end users.
The assumption doesn't match the infrastructure.
A regulation that requires AI-generated images to carry disclosure metadata is technically enforceable at the creation layer. Platforms like Midjourney or DALL-E can embed C2PA manifests in every output. But when those images are shared on Instagram, the metadata is stripped. The legal requirement was met at creation. The practical disclosure never reaches the audience.
This creates a compliance theater problem. Organizations can demonstrate that they embedded the required metadata. But if the distribution infrastructure removes it before anyone sees it, the disclosure accomplished nothing. Regulators are writing rules for an internet that technically could preserve provenance but economically chooses not to.
Enforcement will eventually force a reckoning. Either platforms will be required to preserve provenance metadata, or regulations will shift to mandate interface-level disclosures that platforms control. The former protects independent verification. The latter consolidates trust in platform discretion.
Conclusion
Organizations building AI governance strategies should understand that embedded provenance metadata may not survive the distribution channels where content actually circulates. Verification systems that depend on platforms preserving C2PA or IPTC data are building on an assumption the infrastructure doesn't support.
The emerging alternative is treating provenance as separate from distribution—maintaining cryptographic records in external systems and linking content through hashes rather than embedded metadata. It's more complex. It requires additional infrastructure. But it's designed for the internet that exists, not the one the standards assumed.
SYNTHETIC PROOF
FROM PROVENANCE TO OPERATIONAL TRUST
Understand Your AI Trust Gap
Synthetic Proof helps teams evaluate verification, provenance, prompt risk, and digital media trust through independent audits and structured findings.
Explore Synthetic ProofSynthetic Proof
Verified — Editorial Layer
This content has passed editorial verification for clarity, accuracy, and trust alignment.
Editor-in-Chief: Kevin Marsh
Verification Status: PASSED
Verification Status: PASSED
Comments
Post a Comment