How continuous C2PA manifest appending protects content integrity through every distribution phase. Most organizations treat provenance like a birth certificate—something you create once, file away, and only retrieve when you need to prove where something came from. But in environments where AI models are retrained, datasets are versioned, media assets are transformed, and content travels through editorial pipelines before reaching production, this static approach breaks down almost immediately. The real challenge isn't documenting an asset's origin. It's maintaining an accurate record as that asset evolves through dozens of transformations, approvals, modifications, and ownership changes across its entire lifecycle. The value of provenance ultimately depends on whether organizations can turn evidence into confident decisions. Synthetic Proof helps examine that broader trust picture across AI content and workflows. This is where continuous provenanc...
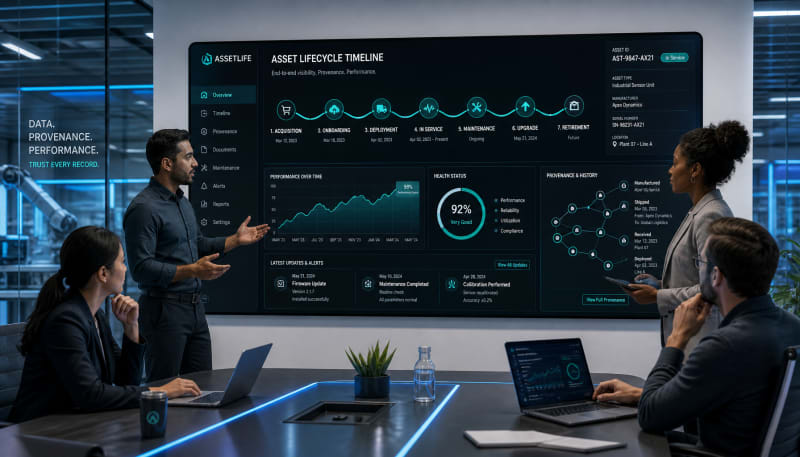
How continuous C2PA manifest appending protects content integrity through every distribution phase.
Most organizations treat provenance like a birth certificate—something you create once, file away, and only retrieve when you need to prove where something came from. But in environments where AI models are retrained, datasets are versioned, media assets are transformed, and content travels through editorial pipelines before reaching production, this static approach breaks down almost immediately.
The real challenge isn't documenting an asset's origin. It's maintaining an accurate record as that asset evolves through dozens of transformations, approvals, modifications, and ownership changes across its entire lifecycle.
The value of provenance ultimately depends on whether organizations can turn evidence into confident decisions. Synthetic Proof helps examine that broader trust picture across AI content and workflows.
This is where continuous provenance becomes critical—and why it's emerging as a foundational pillar of TrustOps. Without the ability to update provenance records as assets change, organizations lose the ability to verify authenticity, trace accountability, or demonstrate compliance when it matters most.
Static Provenance Works Until Assets Start Moving
Early provenance systems focused primarily on creation metadata. Who made this? When was it generated? What model or process produced it? These questions matter, but they only capture the first moment in an asset's lifecycle.
The problem becomes visible the moment an asset enters a production workflow. A marketing team receives an AI-generated image, crops it, adjusts the color balance, and adds overlay text. A data science team takes a training dataset, filters outliers, applies augmentation techniques, and merges it with external sources. A news organization receives video footage, edits it for length, adds context, and publishes it across multiple platforms.
At each step, the asset changes. New actors touch it. New transformations alter it. New context surrounds it. And if the provenance record remains frozen at the point of creation, it becomes increasingly disconnected from the asset organizations are actually using, storing, or distributing.
The Governance Gap Widens With Each Transformation
This gap between static records and dynamic assets creates real operational risk. When regulators ask how a decision was made, teams need to trace the exact version of the dataset that informed the model. When disputes arise over content authenticity, organizations must demonstrate every modification applied between capture and publication. When compliance audits examine AI usage, they require visibility into who approved what, when, and under what conditions.
None of these questions can be answered with origin metadata alone. They require a provenance system designed to evolve with the asset itself.
Continuous Provenance Tracks Change, Not Just Creation
Continuous provenance operates on a fundamentally different principle: provenance records should update throughout an asset's entire lifecycle, not just at the moment of creation. Every meaningful transformation, every change in ownership, every quality gate or approval checkpoint becomes part of the permanent record.
This doesn't mean logging every trivial operation. It means capturing the transformations that actually matter for trust, compliance, or accountability. When an AI model is retrained, that event updates the provenance record. When a dataset passes through a validation checkpoint, that verification becomes part of the chain. When media content receives editorial approval, that decision gets recorded alongside the technical transformations.
The result is a living record that mirrors the asset's actual journey through organizational systems rather than preserving only its initial state.
CP2A as an Operational Pattern
The industry is beginning to describe this pattern as Continuous CP2A—a framework for maintaining provenance across the entire lifecycle of digital assets. CP2A stands for Creation, Processing, Publishing, and Archival, representing the major phases most assets pass through in production environments.
During Creation, provenance captures origin metadata, authorship, and initial context. During Processing, it tracks transformations, validations, and modifications applied to the asset. At Publishing, it records approvals, distribution channels, and audience-specific versions. Through Archival, it preserves the complete history alongside the asset itself for long-term governance and retrieval.
Continuous CP2A treats these phases not as discrete checkpoints but as an ongoing process. Provenance updates happen as the asset moves, ensuring the record accurately reflects current state while preserving historical context.
Why Updating Records Is Technically Harder Than It Sounds
Building continuous provenance requires solving several technical challenges that don't exist in static systems. The first is maintaining cryptographic integrity as records change. Provenance systems increasingly rely on cryptographic signatures or immutable logs to prevent tampering. But if you need to append new information without invalidating earlier signatures, you need append-only architectures that preserve both integrity and flexibility.
The second challenge is contextual linking. When an asset is transformed, the provenance system must understand the relationship between the original and the derivative. Is this a minor edit or a substantial modification? Does it create a new asset or update an existing one? These distinctions matter for governance, but they require semantic understanding that goes beyond simple event logging.
The third challenge is scale. In organizations producing thousands of AI outputs daily, provenance systems must update records without creating operational bottlenecks or storage problems. This means designing for incremental updates, efficient indexing, and selective retention rather than exhaustive logging of every system event.
Governance Cannot Work Without Lifecycle Provenance
The shift toward continuous provenance isn't driven primarily by technical elegance. It's driven by regulatory expectations and operational necessity. AI governance frameworks increasingly require organizations to demonstrate not just where assets came from, but how they were validated, who approved them, and what changes occurred before deployment.
The EU AI Act, for example, expects high-risk AI systems to maintain documentation throughout their operational lifecycle, not just at development. Media authenticity standards emerging from C2PA require tracking modifications made to content after capture. Data governance regulations demand visibility into how datasets were processed, filtered, and transformed before use in production models.
Static provenance can't satisfy these requirements because it can't answer questions about what happened between creation and use. Organizations need the ability to prove that an asset passed through appropriate quality gates, received necessary approvals, and complied with relevant policies at every stage of its journey.
Audit Trails That Actually Reflect Reality
This matters most when something goes wrong. If an AI system produces an unexpected outcome, teams need to trace exactly which version of which dataset informed which model iteration. If published content is disputed, organizations must demonstrate the complete chain of modifications and approvals. If compliance questions arise, executives need defensible records showing that appropriate governance processes were followed.
Continuous provenance makes these audit trails possible because it creates records that mirror actual operational practice rather than idealized workflows documented at project kickoff.
What Changes When Provenance Becomes Continuous
Adopting continuous provenance shifts how organizations think about trust infrastructure. Instead of treating provenance as a compliance checkbox applied at the end of a process, it becomes operational infrastructure embedded throughout production systems.
This changes procurement conversations. Organizations start evaluating whether their content management systems, data platforms, and AI pipelines support provenance updates natively rather than bolting verification on at publication. It changes architecture decisions, as teams design for auditability from the beginning rather than retrofitting logging after systems are built.
It also changes governance models. When provenance updates throughout an asset's lifecycle, accountability becomes distributed across everyone who touches that asset rather than concentrated solely with the original creator. This requires clearer role definitions, better training, and more sophisticated access controls than static systems demand.
The Shift From Project to Infrastructure
Perhaps most importantly, continuous provenance accelerates the transition from treating trust as a project deliverable to recognizing it as foundational infrastructure. Just as version control became standard for code despite adding complexity, lifecycle provenance is becoming table stakes for organizations producing, transforming, or distributing AI-generated assets at scale.
Early adopters are already building these capabilities into their core systems rather than treating provenance as an optional add-on. That distinction—between organizations that embed continuous provenance into operations and those that apply static verification only when required—is starting to separate leaders from laggards in trust maturity.
Final Thoughts
Provenance that stops at creation tells you where an asset came from. Provenance that updates throughout a lifecycle tells you what happened to it, who approved it, and whether it remains trustworthy by the time it reaches production or publication. That difference matters more with every regulatory framework enacted, every governance standard published, and every AI system deployed into environments where accountability cannot be negotiable.
The organizations building continuous provenance capabilities today aren't doing it because the technology is mature or the standards are settled. They're doing it because they recognize that the assets flowing through their systems—AI models, training data, generated content, automated decisions—have lifecycles that matter. And managing those lifecycles responsibly requires trust infrastructure capable of evolving as the assets themselves evolve.
The Practical Position
Provenance only becomes operationally valuable when it reflects an asset's complete journey, not just its birthplace. Organizations that treat provenance as a living record rather than static documentation gain verifiable accountability across transformations, approvals, and ownership changes—exactly what regulators, auditors, and stakeholders now demand when trust cannot be assumed.
— Kevin Marsh, Editor-in-Chief
SYNTHETIC PROOF
FROM PROVENANCE TO OPERATIONAL TRUST
Understand Your AI Trust Gap
Synthetic Proof helps teams evaluate verification, provenance, prompt risk, and digital media trust through independent audits and structured findings.
Explore Synthetic ProofSynthetic Proof
Verified — Editorial Layer
This content has passed editorial verification for clarity, accuracy, and trust alignment.
Editor-in-Chief: Kevin Marsh
Verification Status: PASSED
Verification Status: PASSED
Comments
Post a Comment