Strategies for ensuring your asset’s chain of custody remains verifiable across any channel. A photograph appears in a news report. A legal document crosses a negotiation table. A research dataset underpins a policy decision. In each case, the same question arises: where did this content actually come from? For decades, that question was answerable through metadata, file properties, and institutional trust. But generative AI has fundamentally altered the equation. Content can now be created, modified, and redistributed at scale with minimal effort and near-perfect fidelity. The result is a provenance crisis that affects everything from newsrooms to courtrooms to corporate data operations. A credential can explain part of an asset’s history. Independent evaluation helps determine how much confidence the available evidence should support. Synthetic Proof is built for that wider trust assessment. The industry's response has largely centered on two technologies...
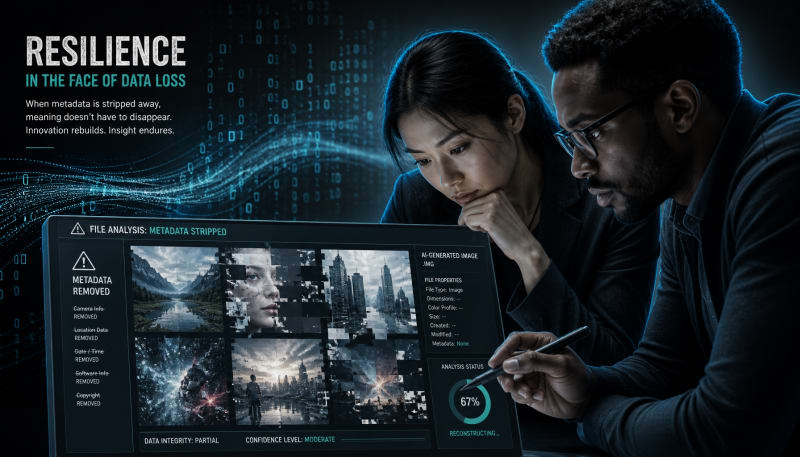
Discover why losing metadata creates new challenges for digital verification.
A healthcare organization embeds C2PA metadata into every AI-generated medical illustration used in patient education materials. The metadata confirms the image source, creation date, and generation parameters. Then a physician downloads one of these images, opens it in an older editing tool to add an annotation, and saves it. The metadata disappears. The image now circulates without provenance, indistinguishable from unverified content.
This scenario plays out thousands of times daily across enterprises, newsrooms, creative studios, and government agencies. Organizations invest in content authenticity infrastructure, implement C2PA standards, and establish rigorous AI governance policies. Then routine workflows—compression, format conversion, social media uploads, email attachments—strip away the very metadata they worked to embed.
The value of provenance ultimately depends on whether organizations can turn evidence into confident decisions. Synthetic Proof helps examine that broader trust picture across AI content and workflows.
The question isn't whether AI-generated content should carry metadata. Most organizations building trust systems already agree it should. The real question is what happens when that metadata inevitably gets removed, and whether trust infrastructure can function in an environment where provenance signals are fragile.
Metadata Loss Is the Default, Not the Exception
Digital content moves through ecosystems designed long before provenance became operationally critical. Every transformation point represents a potential metadata failure.
Image compression tools optimize for file size, not metadata preservation. Content management systems prioritize performance over complete metadata passthrough. Social platforms strip EXIF data as a privacy measure, taking C2PA credentials with it. Email clients transcode attachments. Mobile apps apply filters that create new files rather than modifying originals. Format converters focus on visual fidelity while discarding "non-essential" data.
Even when systems technically support metadata standards, implementation varies. Some preserve metadata partially. Others strip specific fields deemed unnecessary. Many simply weren't designed with content authenticity requirements in mind.
The result is an environment where metadata attached at creation frequently doesn't survive to consumption. An AI-generated image might carry perfect provenance credentials when it leaves Adobe Firefly or Midjourney, only to lose them before reaching the stakeholder who actually needs to verify its origin.
The Assumption Breaking Down
Early content authenticity frameworks assumed a relatively controlled environment. Metadata would be embedded at creation, preserved through distribution, and verified at consumption. The Content Authenticity Initiative, C2PA specification, and similar efforts built technical standards around this model.
That assumption worked in pilot programs and controlled enterprise environments. It breaks down in actual operational reality.
A marketing team generates product images using AI, embeds complete provenance metadata, and stores them in a digital asset management system that preserves C2PA credentials. Then a regional office downloads an image for a local campaign, resizes it in an unsupported tool, and uploads it to a third-party advertising platform. The metadata is gone. The organization's governance policy required provenance tracking, but the content now circulates without it.
The problem isn't that the original metadata was inadequate. The problem is that content authenticity infrastructure assumed metadata would remain attached to content as it moved through unpredictable, uncontrolled workflows.
Organizations discover this gap when they attempt to audit AI content months after creation, trace the origin of synthetic media that entered their systems from external sources, or demonstrate compliance with AI disclosure requirements for content that passed through multiple transformation steps.
What Metadata Stripping Actually Breaks
When AI metadata disappears, several trust mechanisms fail simultaneously.
Verification becomes impossible at the point of consumption. A newsroom receives an image from a freelancer who claims it was AI-generated with specific parameters. Without intact metadata, the newsroom cannot independently confirm that claim. They either trust the source unconditionally or reject potentially legitimate content.
Compliance documentation breaks down. Regulatory frameworks increasingly require organizations to track and disclose AI-generated content. When metadata strips away, the audit trail disappears. Organizations that can prove they embedded provenance data at creation cannot prove that data remained attached to content through its entire lifecycle.
Attribution chains collapse. AI content often involves multiple contributors—the person who wrote the prompt, the model that generated the output, the organization that fine-tuned the model, the editor who modified the result. Metadata preserves that chain. Without it, attribution reduces to guesswork.
Governance policies become unenforceable. An enterprise policy might prohibit using AI-generated content without disclosure, or restrict certain models for sensitive applications. Enforcement depends on identifying AI content reliably. Metadata stripping makes that identification impossible using authenticity credentials alone.
The Detection Fallback Isn't Sufficient
When metadata proves unreliable, organizations often consider AI detection tools as a backup. If content lacks provenance metadata, perhaps detectors can identify AI origin through analysis of the content itself.
Detection fills a different role than provenance. Detectors answer whether content appears AI-generated. Provenance answers what created it, when, how, and under what authority. Detection provides suspicion. Provenance provides evidence.
More practically, detection accuracy degrades as AI generation quality improves. Early AI text and images carried artifacts detectors could identify. Modern models produce output that increasingly resembles human-created content. Detection that works today may not work next quarter.
Organizations building trust infrastructure need both capabilities, but they serve different functions. Detection identifies candidates for scrutiny. Provenance provides verifiable answers. When metadata strips away, organizations lose the verifiable answer and fall back to probabilistic suspicion.
Resilience Through Verification Architecture, Not Just Metadata
The metadata stripping problem is pushing trust infrastructure toward architectural resilience rather than relying solely on content-attached credentials.
Some organizations now maintain parallel verification systems. Metadata travels with content when possible, but provenance records also exist independently in tamper-evident logs, blockchain registries, or verification databases. When content arrives without metadata, these systems can still confirm its origin by matching content hashes or cryptographic signatures against authoritative records.
This approach treats metadata as a convenience rather than the sole source of truth. When metadata survives the distribution process, verification happens instantly at the point of consumption. When metadata strips away, verification queries an independent record system.
The architecture requires more infrastructure than simple metadata embedding. Organizations must maintain registries, manage cryptographic key systems, and build APIs that allow verification queries from multiple consumption points. But it provides resilience against the metadata fragility problem.
Where the Responsibility Shifts
Metadata stripping also changes where verification responsibility sits.
In metadata-dependent systems, responsibility falls primarily on content creators and distribution platforms. Creators embed metadata, platforms preserve it, and consumers read it at the point of use. When metadata strips away, the system provides no fallback.
In resilient architectures, verification responsibility distributes across multiple layers. Creators still embed metadata and register content with independent verification systems. Platforms still attempt to preserve metadata when possible. But consumers can also query verification infrastructure directly when metadata is absent.
This distribution creates redundancy. Multiple verification paths exist for the same content. Metadata stripping breaks one path but doesn't eliminate verification capability entirely.
The Standards Gap
Current metadata standards weren't designed with stripping resilience as a primary requirement. C2PA and similar specifications focus on what metadata should contain and how it should be cryptographically secured. They provide less guidance on maintaining verification capability when that metadata disappears.
Some emerging approaches address this gap. Perceptual hashing allows content matching even when metadata strips away. Watermarking embeds provenance signals directly into content rather than metadata fields. Distributed ledgers provide external verification records independent of file metadata.
But these approaches aren't yet standardized across the industry. Organizations building trust infrastructure often implement custom solutions, creating fragmentation in how verification works when metadata is unavailable.
The standards conversation is shifting from "how should we format metadata" to "how should verification work in environments where metadata doesn't reliably survive." That's a more complex question requiring coordination across content creation tools, distribution platforms, and verification infrastructure providers.
What Operational Trust Actually Requires
Organizations serious about AI content trust are learning that metadata alone doesn't provide operational resilience.
Effective trust infrastructure now involves multiple verification layers—metadata when available, independent registries when metadata strips away, detection tools when neither provides answers, and human review when uncertainty remains unacceptable.
It requires verification architecture that assumes content will move through systems that don't preserve metadata, rather than assuming preservation as the default case.
It means treating provenance as an organizational capability rather than a file attribute. The question shifts from "does this file contain valid metadata" to "can we verify this content's origin through available trust infrastructure."
Organizations implementing this approach maintain content registries, manage cryptographic signing systems, establish verification APIs, and build workflows that route questionable content to appropriate review processes. The infrastructure is more complex than simply embedding C2PA metadata at creation, but it functions in real-world environments where metadata fragility is the norm.
Final Thoughts
AI metadata stripping reveals a fundamental tension in content authenticity infrastructure. Technical standards provide sophisticated ways to embed provenance data, but those standards operate in distribution environments designed without provenance preservation as a requirement.
The gap isn't closing quickly. Legacy tools, platforms, and workflows won't suddenly start preserving metadata they currently strip. Organizations can't control every transformation point content passes through before reaching stakeholders who need to verify its origin.
What's changing is how trust infrastructure architects think about resilience. Early content authenticity frameworks treated metadata as the trust mechanism. Emerging architectures treat metadata as one verification path among several, with independent verification systems providing resilience when that path fails.
The organizations building durable trust infrastructure aren't asking whether metadata will sometimes strip away. They're building systems that maintain verification capability when it does. That shift from metadata dependence to architectural resilience represents the difference between trust infrastructure that works in pilot programs and trust infrastructure that works in operational reality.
SYNTHETIC PROOF
FROM PROVENANCE TO OPERATIONAL TRUST
Understand Your AI Trust Gap
Synthetic Proof helps teams evaluate verification, provenance, prompt risk, and digital media trust through independent audits and structured findings.
Explore Synthetic ProofSynthetic Proof
Verified — Editorial Layer
This content has passed editorial verification for clarity, accuracy, and trust alignment.
Editor-in-Chief: Kevin Marsh
Verification Status: PASSED
Verification Status: PASSED
Comments
Post a Comment